Explanation
Architecture
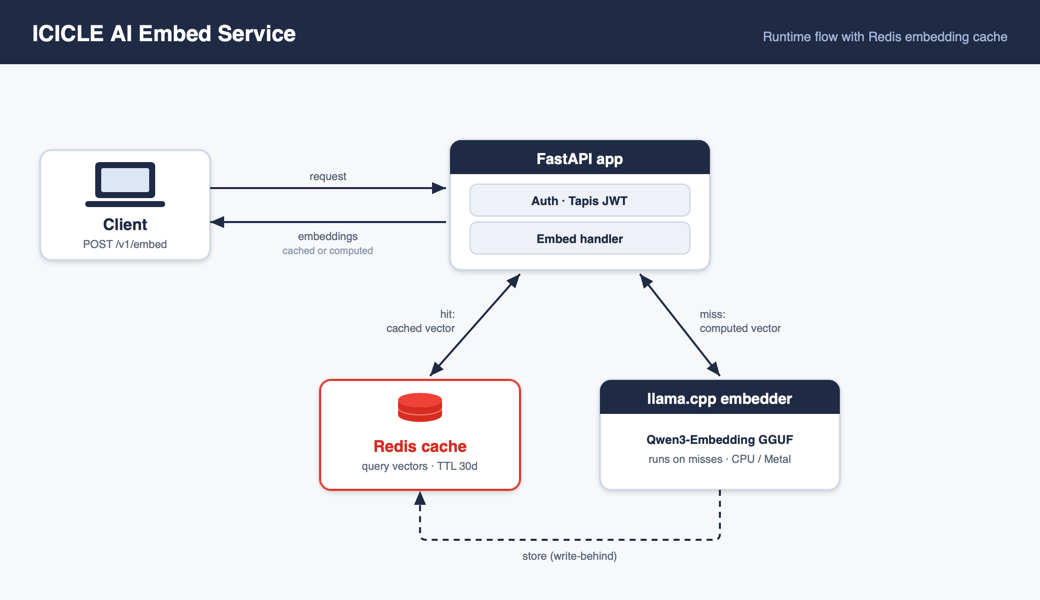
This is how it works: the client calls /v1/embed, the FastAPI app authenticates the request (Tapis JWT), and the embeddings come back either from the Redis cache (a hit returns the cached vector) or from the llama.cpp embedder (a miss computes the vector). Freshly computed query vectors are written back to Redis asynchronously (write-behind), so the next identical query is a cache hit. The cache is optional and fail-open — if Redis is unavailable, requests still embed normally.
For a closer look at what happens inside a single request — auth, validation, the serialized embedder, and pooling — the textual flow below maps to the actual code path in src/app/:
                    ICICLE AI Embed Service
                       ┌──────────────────────────────────────────────────┐
                       │                                                  │
  Client Request       │   FastAPI Application                            │
  (X-Tapis-Token)      │                                                  │
        |              │   ┌──────────┐    ┌───────────────────────────┐  │
        v              │   │  Auth    │    │   /v1/embed handler       │  │
  ┌──────────┐         │   │  (JWKS)  │    │                           │  │
  │  POST    │────────>│   │          │───>│  Pydantic validation:     │  │
  │ /v1/embed│         │   │ Verify   │    │   - non-empty strings     │  │
  │          │         │   │ JWT sig  │    │   - len <= max_chars      │  │
  └──────────┘         │   │ Check    │    │   - count <= max_inputs   │  │
                       │   │ expiry   │    │                           │  │
                       │   │ Validate │    │  Format query / document  │  │
                       │   │ tenant + │    │  template                 │  │
                       │   │ access   │    └───────────┬───────────────┘  │
                       │   └──────────┘                │                  │
                       │                               v                  │
                       │                  ┌───────────────────────────┐   │
                       │                  │  Embedder (singleton)     │   │
                       │                  │                           │   │
                       │                  │  ┌─────────────────────┐  │   │
                       │                  │  │  threading.Lock     │  │   │
                       │                  │  │   (serializes       │  │   │
                       │                  │  │    embed() calls)   │  │   │
                       │                  │  └──────────┬──────────┘  │   │
                       │                  │             v             │   │
                       │                  │  ┌─────────────────────┐  │   │
                       │                  │  │  llama_cpp.Llama    │  │   │
                       │                  │  │   embedding=True    │──┼───┼──> Metal / AVX2 / NEON
                       │                  │  │   pooling: last     │  │   │   (quantized matmul)
                       │                  │  │   GGUF on disk      │  │   │
                       │                  │  └─────────────────────┘  │   │
                       │                  └───────────────────────────┘   │
                       │                               │                  │
                       │                               v                  │
                       │                       L2 normalize (opt)         │
                       │                               │                  │
                       │                               v                  │
                       │                          JSON response           │
                       └──────────────────────────────────────────────────┘
How Embedding Works
  raw text  ──>  optional query template  ──>  tokenize  ──>  forward pass  ──>  pool  ──>  normalize
  "how do          "Instruct: ...\n             [bos, ...,      transformer       last     v / |v|
   plants           Query: how do                eos]            (quantized)       token
   make food"       plants make food"                                              hidden
                                                                                   state
- Tokenization: handled by llama.cpp from the GGUF's bundled tokenizer.
- Forward pass: 28 transformer layers, 1024-dim hidden, run on Metal on macOS / AVX2-AVX-512 on x86 / NEON on ARM. Quantized weights mean every matmul is int8 (Q8_0) or 4-bit (Q4_K_M variants).
- Pooling: last-token pooling, baked into the GGUF metadata. The service does not override this.
- Normalize: L2 normalize on by default so dot product == cosine similarity downstream.
Design Decisions
- llama.cpp over PyTorch/transformers: no PyTorch install (saves ~2 GB), native Metal on Mac, hand-tuned AVX2/AVX-512/NEON kernels for CPU quantized matmul. Materially faster than PyTorch on CPU for this model size, with a fraction of the memory footprint.
- Q8_0 by default: for embedding models the quality delta vs fp16 is within retrieval noise. Drop to f16 only when you need reference vectors.
- Single-process, serialized embedding:
llama-cpp-python'sembed()mutates the shared context and is not thread-safe. The embedder holds athreading.Lockand runs work onanyio.to_threadso the FastAPI event loop stays free. For higher throughput, scale horizontally (more replicas) rather than threading a single model. - Pooling type comes from the GGUF: Qwen3-Embedding uses last-token pooling, baked into the file's metadata. Overriding
pooling_typewould silently corrupt the vectors. - Instruction-aware by default: Qwen3-Embedding expects query/document asymmetry. The
input_typeflag keeps clients from having to format the template themselves;instructionlets advanced users override it per-request. - L2-normalize by default: the vector service uses cosine similarity; normalized vectors make scores comparable across models and turn dot product into cosine.
- Cache queries, not documents: queries repeat, while documents are embedded once and then live in the vector service. The Redis cache therefore stores only query vectors, writes them after the response is sent (write-behind), and fails open.
- Optional, anonymous usage metrics: MLflow logging runs as a background task after the response, so it adds no request latency. It authenticates with the caller's own Tapis token, so the service needs no MLflow service account.
- No server-side chunking: the service embeds what it's given. Callers own chunking, because chunk strategy is domain-specific.
- Auth boundary mirrors the vector service: same Tapis JWT validation (signature + issuer + access-token-type + tenant). One token works across the embed→store→retrieve pipeline.
Security Posture
- Mandatory Tapis JWT on every endpoint except
/healthz. There is no bypass flag — auth is on whether you're running locally or in production. JWTs are validated withRS256only (nonone-algorithm fallback), checked for expiration, issuer,tapis/token_type == "access", andtapis/tenant_id == "icicleai". - No request-body logging. Logs include payload shape (
len(texts),total_chars) and the authenticatedusername, never the raw input text. Tokens are never logged. - Request size limits.
MAX_INPUTS_PER_REQUESTandMAX_CHARS_PER_INPUTcap how much work a single request can ask for, validated by Pydantic before the embedder is touched. - Single shared model context. Requests are serialized at the embedder level so a malicious client cannot race the GGUF context into an inconsistent state.
- Limited outbound network. Besides the one-time
huggingface_hubdownload at startup (skipped whenMODEL_PATHis set), the only outbound calls are to Redis (query cache) and, whenMLFLOW_ENABLED=true, to the MLflow server. Both are optional and fail-open. - Anonymous metrics only. MLflow receives request shape only: batch size, character count, cache hits/misses, latency, model and input type. It never receives the username, tenant, token claims or input text. The caller's own validated
X-Tapis-Tokenis used only to authenticate those MLflow calls and is never logged. - Container hygiene. The Docker image runs as a non-root
appuser, ships only runtime libs (no compilers in the final layer), and writes the model cache into a mountable volume so weights persist across restarts without baking into the image. - Fail-closed startup. If model load fails, the process exits with a clear message rather than serving a half-initialized embedder.
Data handling notice: input text is held in memory only for the duration of the request and is never stored. When the cache is enabled, query vectors are stored in Redis under a SHA-256 hash of the request (model, instruction, normalize flag, text), expiring after
CACHE_TTL_SECONDS. Document vectors are never cached.
Reference
API Endpoints
All endpoints (except /healthz) require the X-Tapis-Token header.
| Method | Endpoint | Description |
|---|---|---|
GET | /healthz | Health check (no auth) |
GET | /v1/model | Model name, dim, context length |
POST | /v1/embed | Generate embeddings for text(s) |
Request Fields
Embed (POST /v1/embed)
| Field | Required | Description |
|---|---|---|
input | yes | Single string or list of strings. Each must be non-empty. List length capped by MAX_INPUTS_PER_REQUEST. |
input_type | no | "document" (default) embeds text as-is. "query" wraps with the Qwen3 instruction template for asymmetric search. |
instruction | no | Custom task instruction for queries (max 2000 chars). Ignored when input_type="document". |
normalize | no | L2-normalize vectors (default true). Keep on for cosine search against the vector service. |
Model Info (GET /v1/model)
No body. Returns the loaded model's identifier, dimension, and context length.
Response Fields
Embed Response
| Field | Description |
|---|---|
model | Identifier of the loaded GGUF (repo/file or local stem). |
dim | Vector dimension (1024 for the 0.6B model). |
input_type | Echo of the request's input_type. |
normalized | Echo of the request's normalize flag. |
data | List of {index, embedding} pairs in input order. |
OpenAPI Schema
A full OpenAPI 3.1 specification is shipped alongside this README at openapi.json. The live FastAPI app also exposes it at GET /openapi.json and an interactive Swagger UI at GET /docs.
Docker
Build
DOCKER_BUILDKIT=1 docker build -t icicle-ai-embed-service .
The Dockerfile uses BuildKit cache mounts for both apt and pip plus ccache for the C++ compiler, so the second build of an unchanged llama-cpp-python is near-instant. For GPU inside a container, rebuild with --build-arg overrides or pass CMAKE_ARGS="-DGGML_CUDA=on" (or -DGGML_VULKAN=on) at build time. On macOS, run the service natively to get Metal acceleration — Docker Desktop doesn't expose Metal to containers.
Run
The image declares /home/app/.cache/huggingface as a VOLUME. Mount any persistent storage there and the GGUF will be downloaded once and reused across restarts.
Local development
docker run --rm -p 8001:8000 \
  -v "$HOME/.cache/huggingface:/home/app/.cache/huggingface" \
  --env-file .env \
  icicle-ai-embed-service
Tapis Pods (ICICLE deployment)
The Tapis-managed volume hfembedmodel (1 GiB, AVAILABLE) is sized for the small embedding GGUFs. Map it onto the container's cache directory in the pod definition:
volume_mounts:
  - volume_id: hfembedmodel
    mount_path: /home/app/.cache/huggingface
The volume name is not baked into the image. Any Tapis tenant, Kubernetes PVC, or Docker named volume can be plugged into the same path — the Dockerfile is deployment-agnostic on purpose.
Healthcheck
The image ships a HEALTHCHECK that hits /healthz every 30s with a 120s start-period (model load can be slow on cold start). Orchestrators that have their own probes (Kubernetes, Tapis Pods) can ignore it; plain docker run will surface container health via docker ps.